Extracting data from loss runs
Insurers, pools and claims administrators print loss runs from their own claims systems, so every carrier's report has its own columns and totals. Brokers request them for every account at renewal, and a commercial underwriting desk receives hundreds each week as PDF attachments to submission emails.
Underwriting needs each policy period's claim count, total paid, outstanding reserve and total incurred. A submission intake or rating system loads them to calculate loss ratios against earned premium and claim frequency trends, which shape the renewal quote.
What makes loss runs hard
Every carrier has its own format
Column names and order differ by carrier, so incurred is a printed column in one report and paid plus reserve in another.
Totals appear more than once
Each policy period ends in a subtotal row, and many reports repeat those subtotals in a summary block, so the same figure prints twice.
Claim tables run for pages
An account with a busy claims history produces hundreds of rows across dozens of landscape pages, with a section break between policy periods.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One loss run, end to end
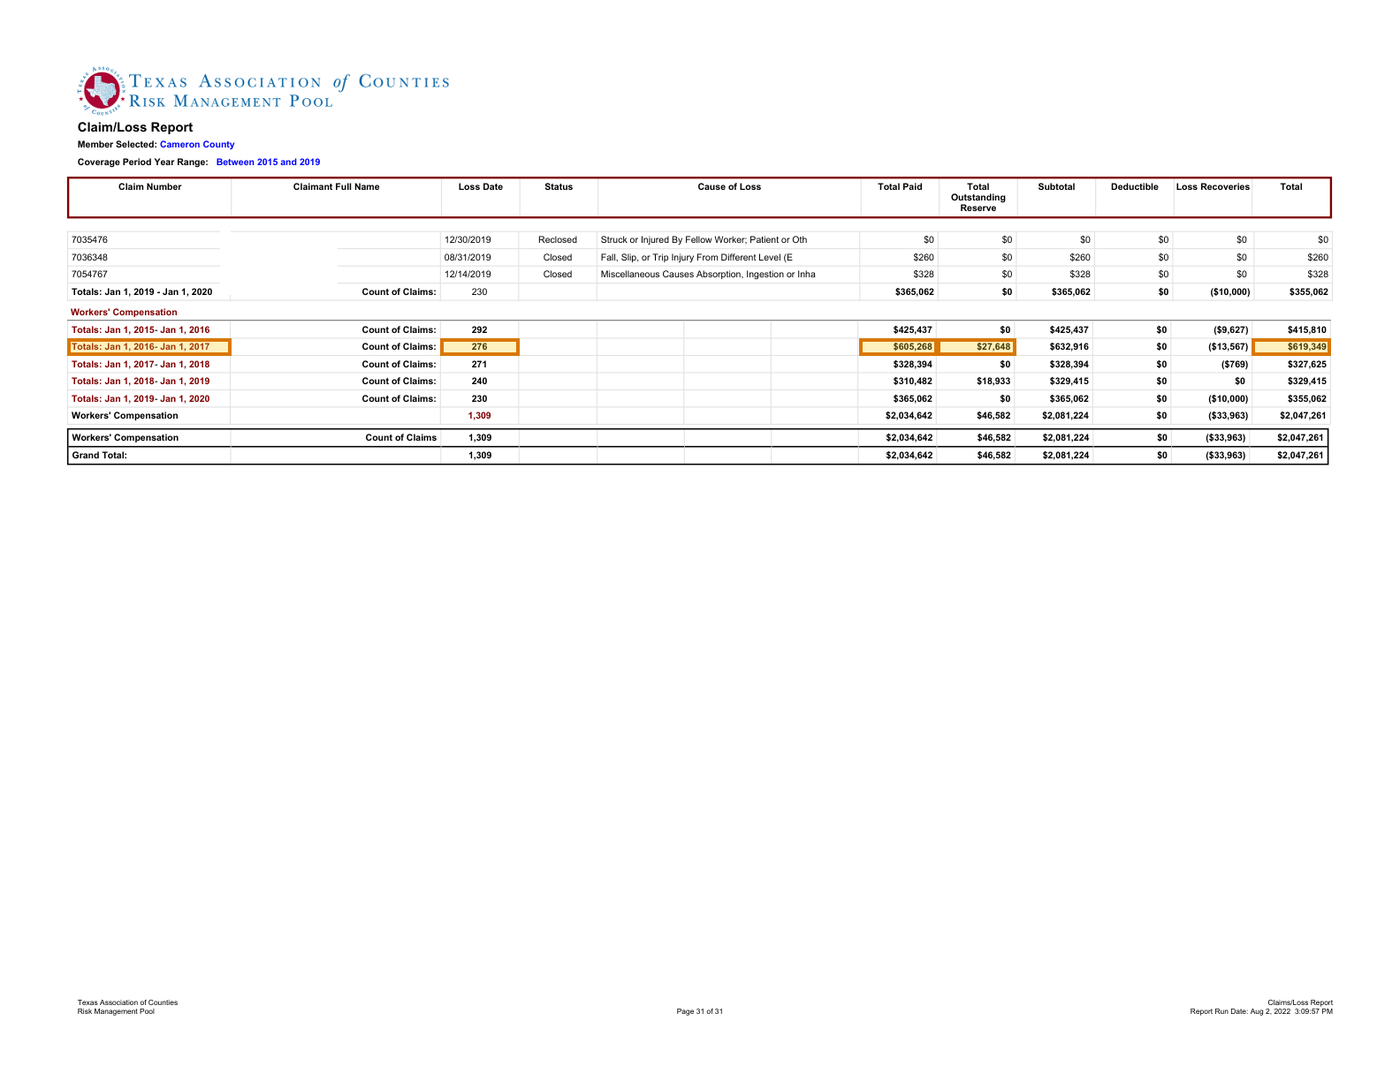
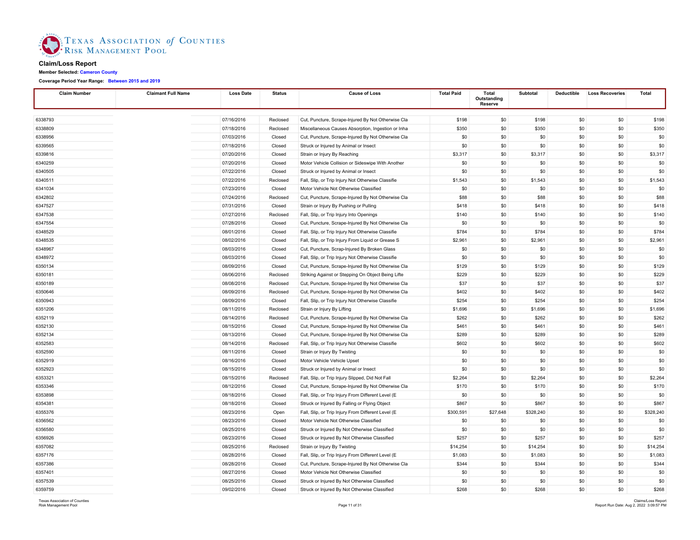
About this document: A workers' compensation loss run from the Texas Association of Counties Risk Management Pool. A member county published it with a request for proposal, so brokers could price the account. Its 31 landscape pages list 1,309 claims across five coverage periods, with a subtotal after each period. Page 31 closes with a summary block, and is featured. The claimant name column is blank at source.
Processing objective: The objective is to read one coverage period the way an underwriter does: how many claims, what was paid, what is still reserved and the total incurred. The row reconciles: paid plus reserve, less recoveries, gives the total incurred.
Demonstration fields: Coverage period, Count of claims, Total paid, Outstanding reserve, Total incurred
The document
4 of 31 pages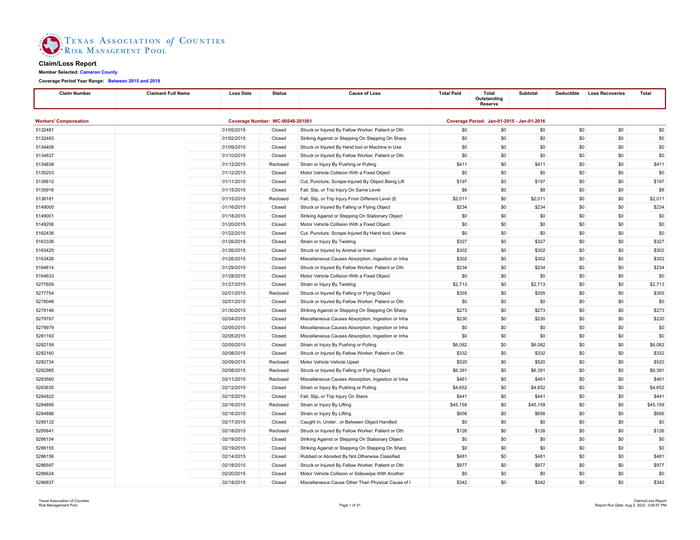 Page 1
 Page 11
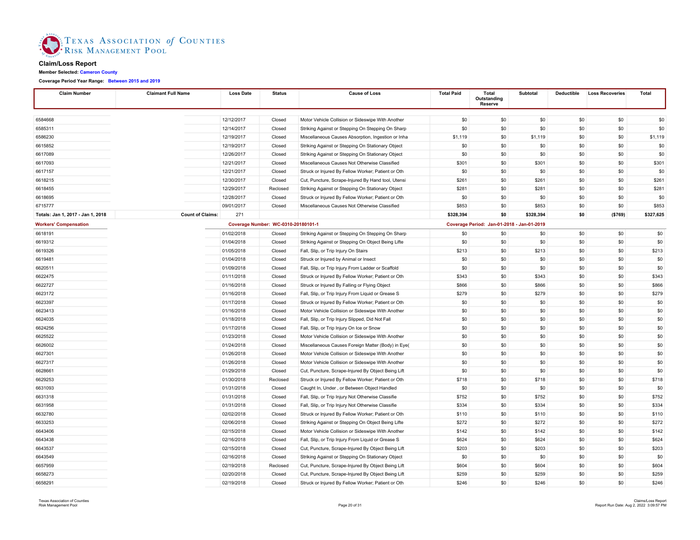 Page 20
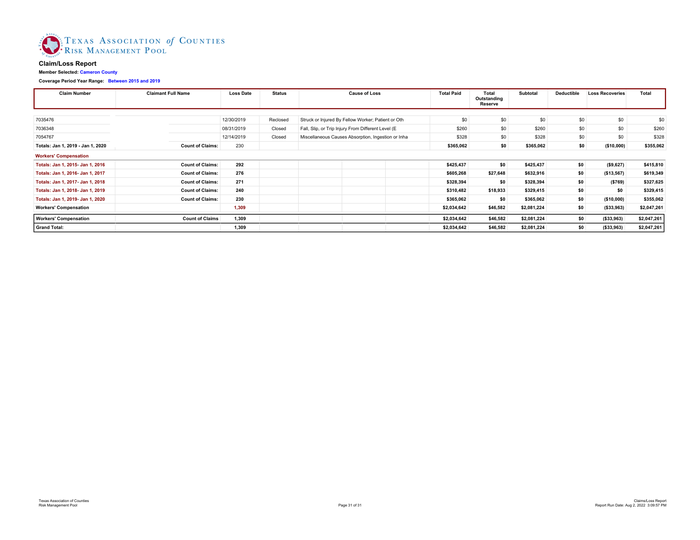 Page 31shown below
Where each value came from
coverage_periods[1].period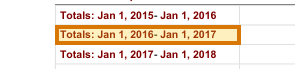
{
  "value": "Jan 1, 2016- Jan 1, 2017",
  "page": 31,
  "range": {
    "end": 294424,
    "start": 294392
  },
  "box": {
    "xmin": 0.04833,
    "ymin": 0.31302,
    "xmax": 0.16483,
    "ymax": 0.32895
  }
}coverage_periods[1].claim_count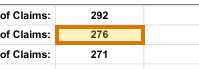
{
  "value": 276,
  "page": 31,
  "range": {
    "end": 294461,
    "start": 294458
  },
  "box": {
    "xmin": 0.31482,
    "ymin": 0.31301,
    "xmax": 0.37059,
    "ymax": 0.32894
  }
}coverage_periods[1].total_paid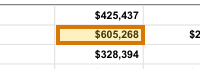
{
  "value": 605268,
  "page": 31,
  "range": {
    "end": 294514,
    "start": 294506
  },
  "box": {
    "xmin": 0.61378,
    "ymin": 0.31299,
    "xmax": 0.66958,
    "ymax": 0.32892
  }
}coverage_periods[1].total_outstanding_reserve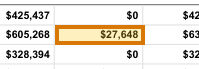
{
  "value": 27648,
  "page": 31,
  "range": {
    "end": 294530,
    "start": 294523
  },
  "box": {
    "xmin": 0.66951,
    "ymin": 0.31299,
    "xmax": 0.72554,
    "ymax": 0.32892
  }
}coverage_periods[1].total_incurred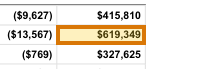
{
  "value": 619349,
  "page": 31,
  "range": {
    "end": 294593,
    "start": 294585
  },
  "box": {
    "xmin": 0.89421,
    "ymin": 0.31297,
    "xmax": 0.95054,
    "ymax": 0.32891
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.