Extracting data from capitalization tables
A company keeps its cap table from formation onward, in equity management software or a spreadsheet its counsel maintains, and each one orders its share classes differently. Investors, acquirers and auditors review one for every financing and exit, often in several versions per deal. Most arrive in a data room as spreadsheets or PDF exports.
Diligence needs each holder's shares by class, the option pool, the class totals and the fully diluted count. A returns model prices each share from those, and the closing funds flow splits the purchase price across every holder.
What makes capitalization tables hard
A grid that is mostly dashes
Most holders own one or two share classes, so most cells print a dash, and share counts alternate with percentages column by column.
Several ownership bases at once
One table states ownership per class, with and without the pool, and fully diluted. A footnote can set how preferred converts to common.
Every company builds its own
Columns follow each company's financing history. Any vendor solution relying on fixed positions is rebuilt for each software export or counsel's spreadsheet.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One capitalization table, end to end
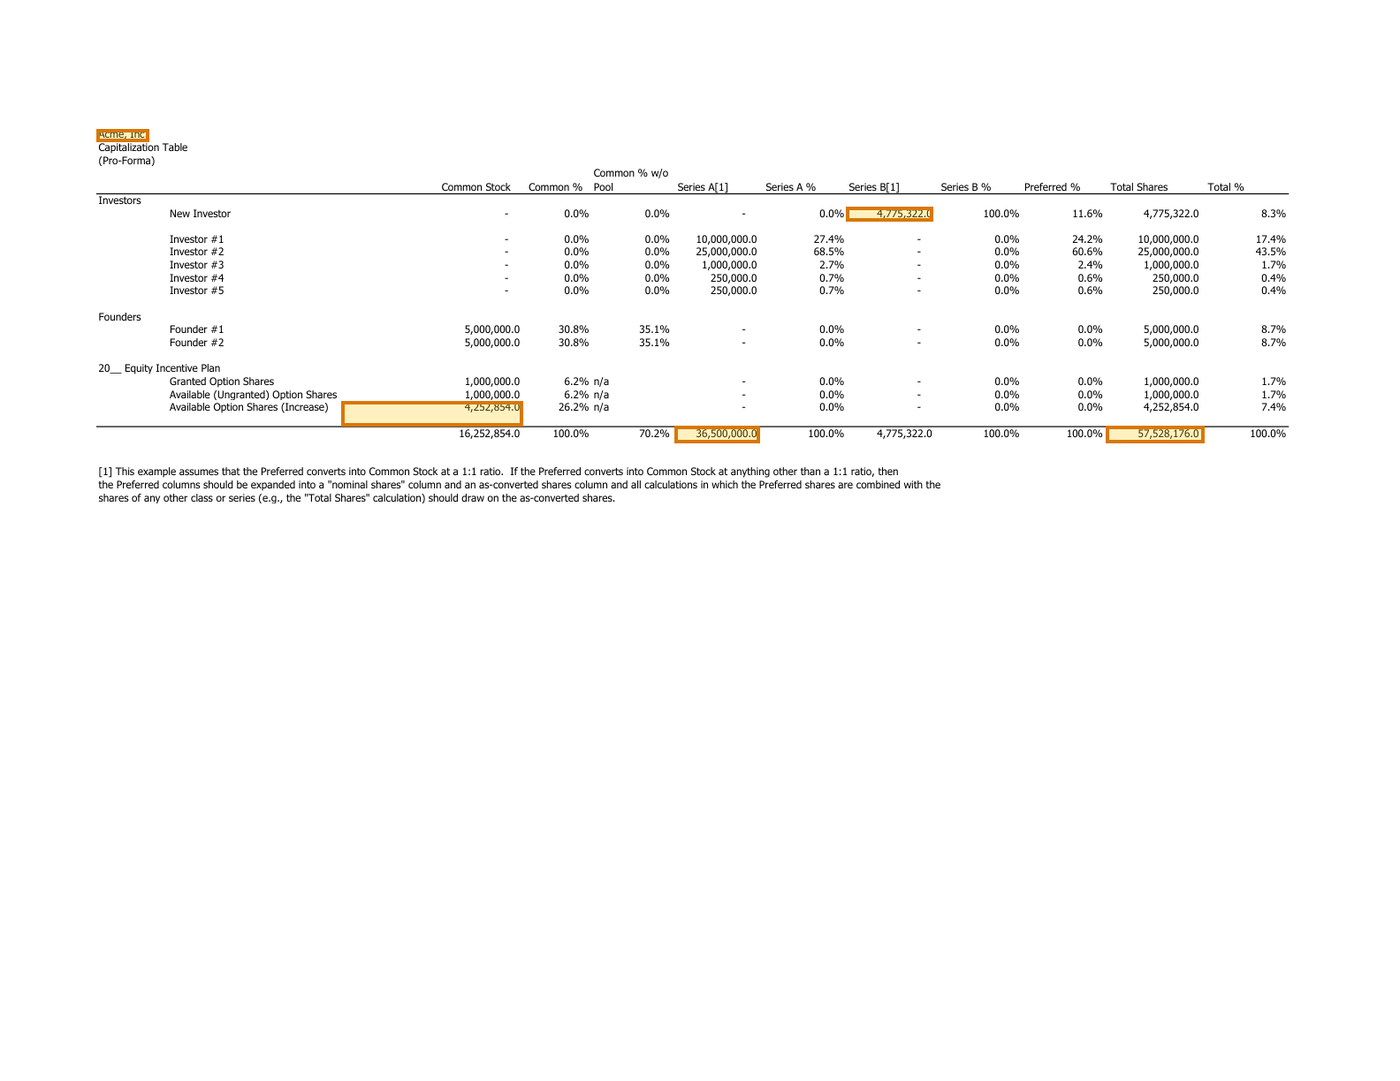
About this document: A pro forma capitalization table for a fictional Acme, Inc. after its Series B financing, published by Cooley LLP as a sample on its Cooley GO resource site. One landscape page carries eleven holder rows across three share classes, then a totals row and a footnote on how preferred converts to common. Page 1 is featured. Every holder is a placeholder.
Processing objective: The objective is to read the Series B round off the table, from the new money's shares to the fully diluted count after the pool top-up. Each number has to stay in its share class column, across rows that are mostly dashes.
Demonstration fields: Company, New investor Series B shares, Option pool increase, Total Series A shares, Fully diluted shares
The document
1 page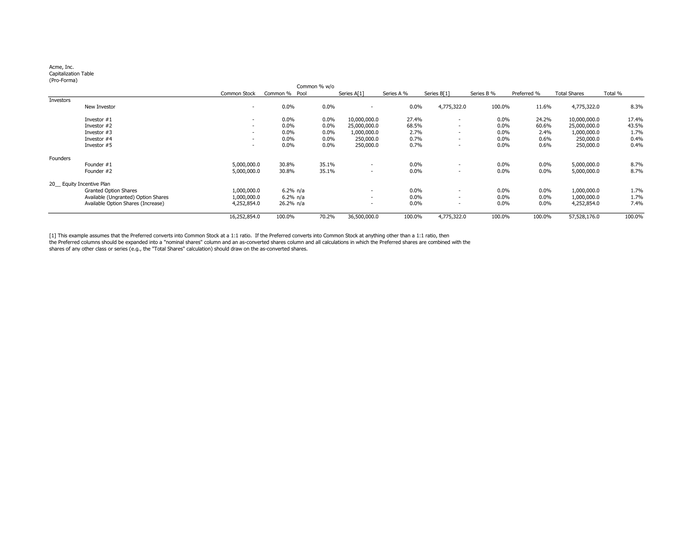 Page 1shown below
Where each value came from
company_name
{
  "value": "Acme, Inc.",
  "page": 1,
  "range": {
    "end": 10,
    "start": 0
  },
  "box": {
    "xmin": 0.06943,
    "ymin": 0.11934,
    "xmax": 0.10617,
    "ymax": 0.13073
  }
}holders[0].series_b_shares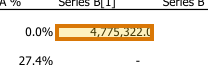
{
  "value": 4775322,
  "page": 1,
  "range": {
    "end": 624,
    "start": 613
  },
  "box": {
    "xmin": 0.60471,
    "ymin": 0.19167,
    "xmax": 0.66635,
    "ymax": 0.20489
  }
}option_pool_increase_shares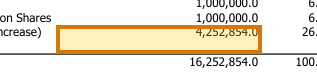
{
  "value": 4252854,
  "page": 1,
  "range": {
    "end": 2550,
    "start": 2539
  },
  "box": {
    "xmin": 0.24393,
    "ymin": 0.37122,
    "xmax": 0.37364,
    "ymax": 0.39459
  }
}totals.total_series_a_shares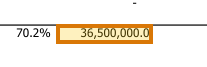
{
  "value": 36500000,
  "page": 1,
  "range": {
    "end": 2761,
    "start": 2749
  },
  "box": {
    "xmin": 0.48174,
    "ymin": 0.39459,
    "xmax": 0.54248,
    "ymax": 0.40937
  }
}totals.fully_diluted_shares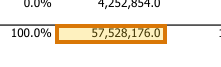
{
  "value": 57528176,
  "page": 1,
  "range": {
    "end": 2847,
    "start": 2835
  },
  "box": {
    "xmin": 0.79024,
    "ymin": 0.39459,
    "xmax": 0.85988,
    "ymax": 0.4095
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.