Extracting data from high school transcripts
Each district prints its own transcript, with its own grading scale, and sends it as a counselor upload or eTranscript. College admissions offices read one per applicant and a final copy for each enrolling student. Scholarship programs, employers, military recruiters and auto insurers ask for them too, as a phone scan of an unofficial copy.
Admissions needs each course's mark and credits, and the average for every term. A reader uses them to recalculate the applicant's GPA on the college's own scale and to rate course rigor. An insurer checks the same averages against its good student discount threshold.
What makes high school transcripts hard
Every district sets its own scale
One district prints numeric marks out of 100 with a percentage average. Another prints letter grades and a weighted GPA on a 5.0 scale.
Terms run across columns
Transcripts stack several terms in each column, so a term that starts at the foot of one column finishes at the top of the next.
Symbols carry course status
An asterisk beside a grade or course code flags a weighted course or an unaveraged mark, and a footer key defines each symbol.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One high school transcript, end to end
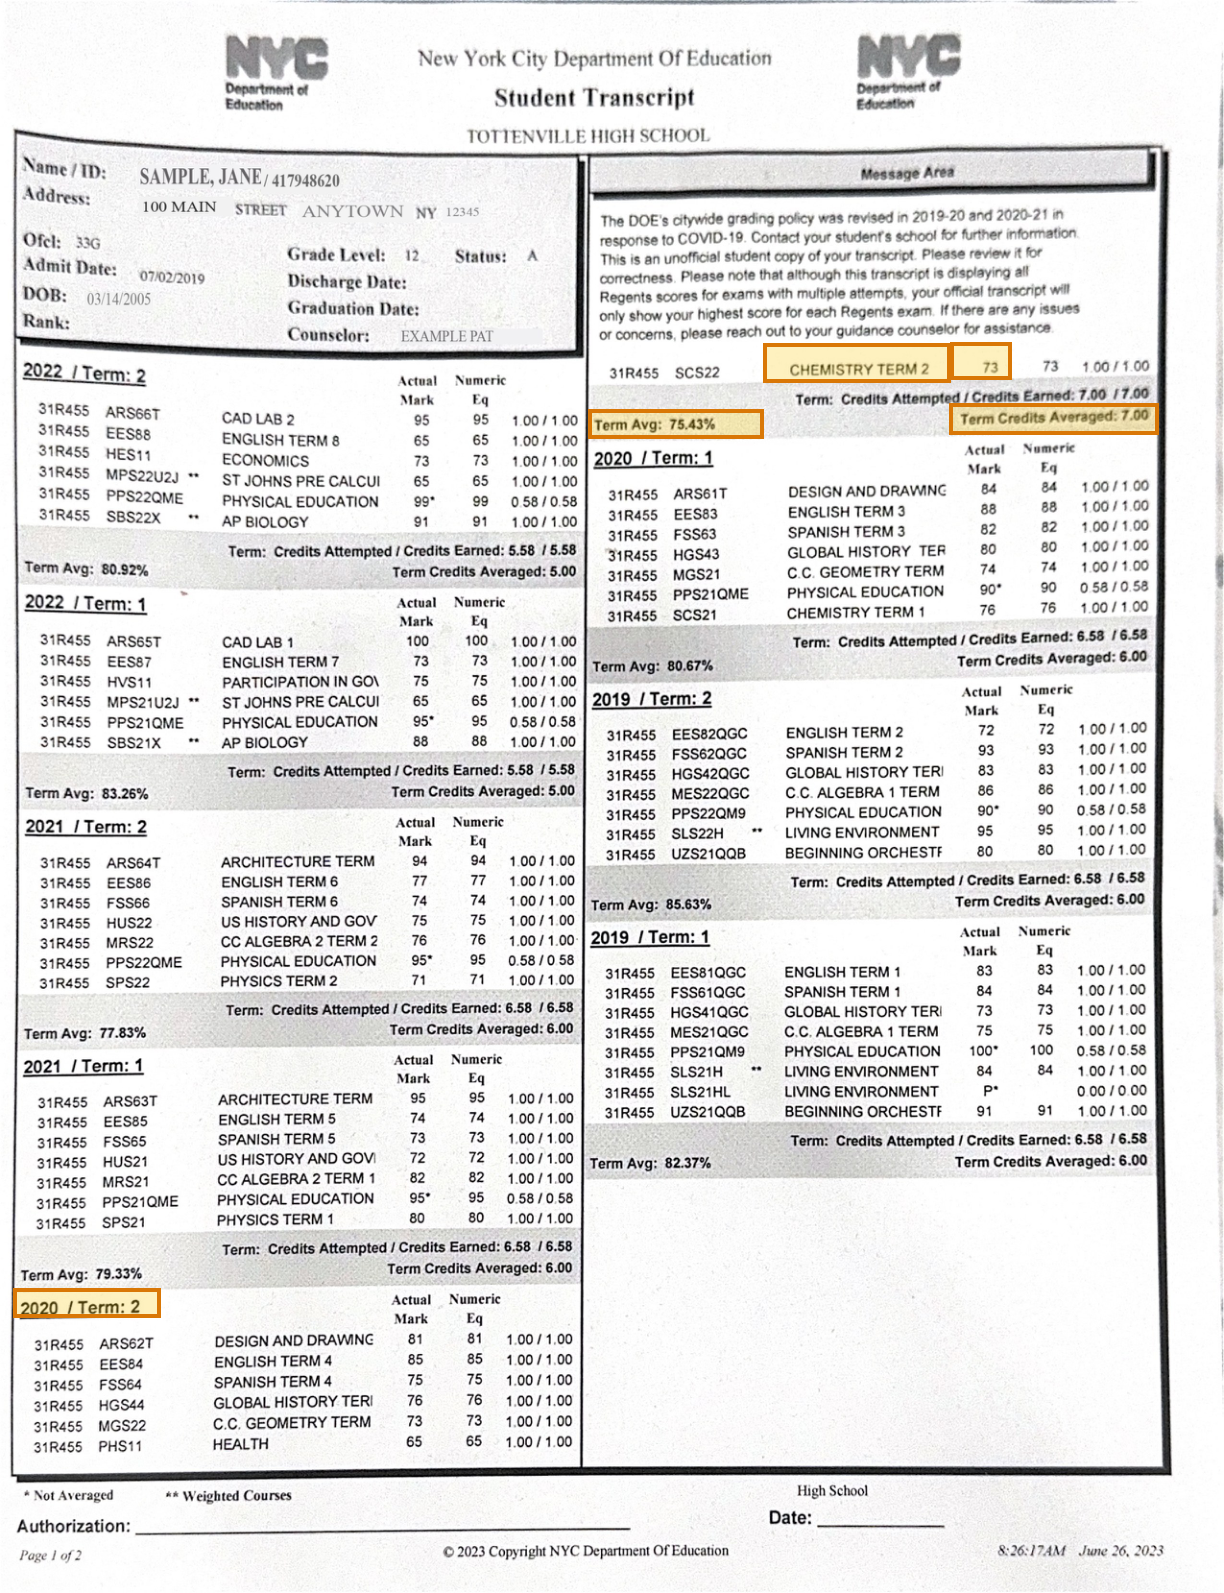
About this document: An unofficial student copy of a New York City Department of Education transcript. The first of its two pages was processed: one portrait page, photographed slightly askew and read from the image alone. Eight terms run newest first in two columns, each closing with its credit totals and average. The student's identifying details and the counselor's name were replaced with stand-ins.
Processing objective: The objective is to read one term as a single record where it breaks across two columns. Its heading and six courses sit at the foot of the left column. The seventh course and the term's totals continue at the top of the right column, and all of them return in one term entry.
Demonstration fields: Term year, Course carried to the next column, Mark, Term credits averaged, Term average
The document
1 page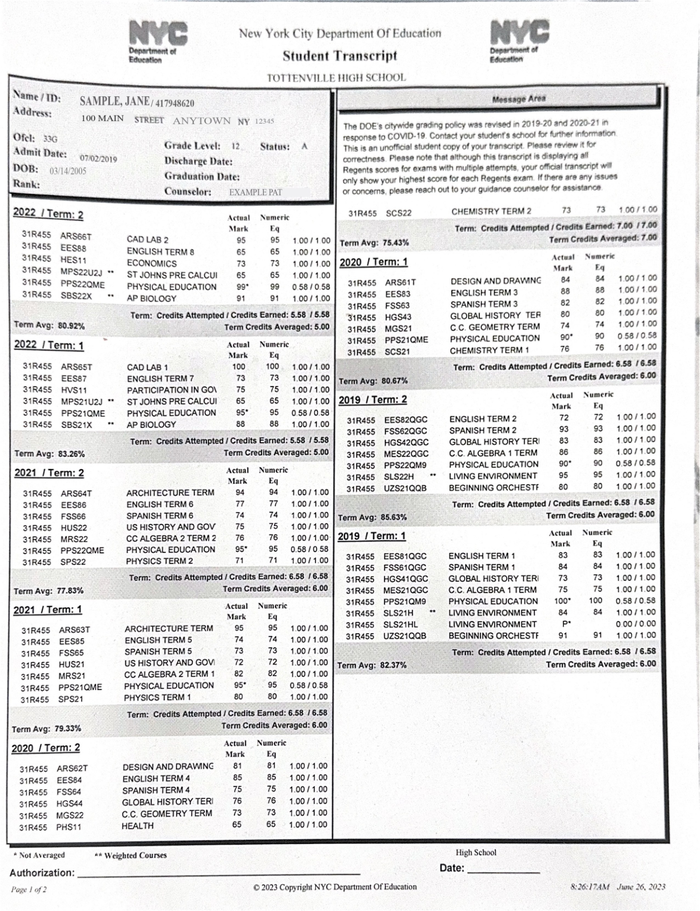 Page 1shown below
Where each value came from
terms[4].year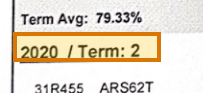
{
  "value": 2020,
  "page": 1,
  "range": {
    "end": 4763,
    "start": 4749
  },
  "box": {
    "xmin": 0.01116,
    "ymin": 0.80899,
    "xmax": 0.13085,
    "ymax": 0.82717
  }
}terms[4].courses[6].course_title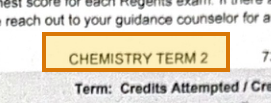
{
  "value": "CHEMISTRY TERM 2",
  "page": 1,
  "range": {
    "end": 6214,
    "start": 6198
  },
  "box": {
    "xmin": 0.62414,
    "ymin": 0.21547,
    "xmax": 0.77622,
    "ymax": 0.23997
  }
}terms[4].courses[6].actual_mark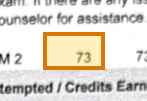
{
  "value": "73",
  "page": 1,
  "range": {
    "end": 6225,
    "start": 6223
  },
  "box": {
    "xmin": 0.77619,
    "ymin": 0.21517,
    "xmax": 0.82626,
    "ymax": 0.23848
  }
}terms[4].term_credits_averaged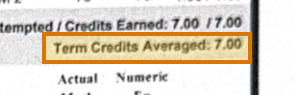
{
  "value": 7,
  "page": 1,
  "range": {
    "end": 6465,
    "start": 6438
  },
  "box": {
    "xmin": 0.77614,
    "ymin": 0.25347,
    "xmax": 0.94669,
    "ymax": 0.27258
  }
}terms[4].term_average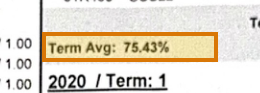
{
  "value": 75.43,
  "page": 1,
  "range": {
    "end": 6408,
    "start": 6392
  },
  "box": {
    "xmin": 0.48115,
    "ymin": 0.25683,
    "xmax": 0.6241,
    "ymax": 0.27538
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.