Extracting data from litigation complaints
Most civil lawsuits open with a complaint, drafted by the plaintiff's lawyers to the rules of the court that receives it. Federal district courts take in more than a quarter of a million civil cases a year. Diligence, insurance and litigation teams pull complaints from court dockets, through PACER or a state e-filing portal.
A reader needs the court, the case number, the parties, each claim with its statute and the relief requested. A litigation tracking system logs each case against the named parties, where a diligence team or insurer reviews it to size the exposure.
What makes litigation complaints hard
Pleading paper adds its own text
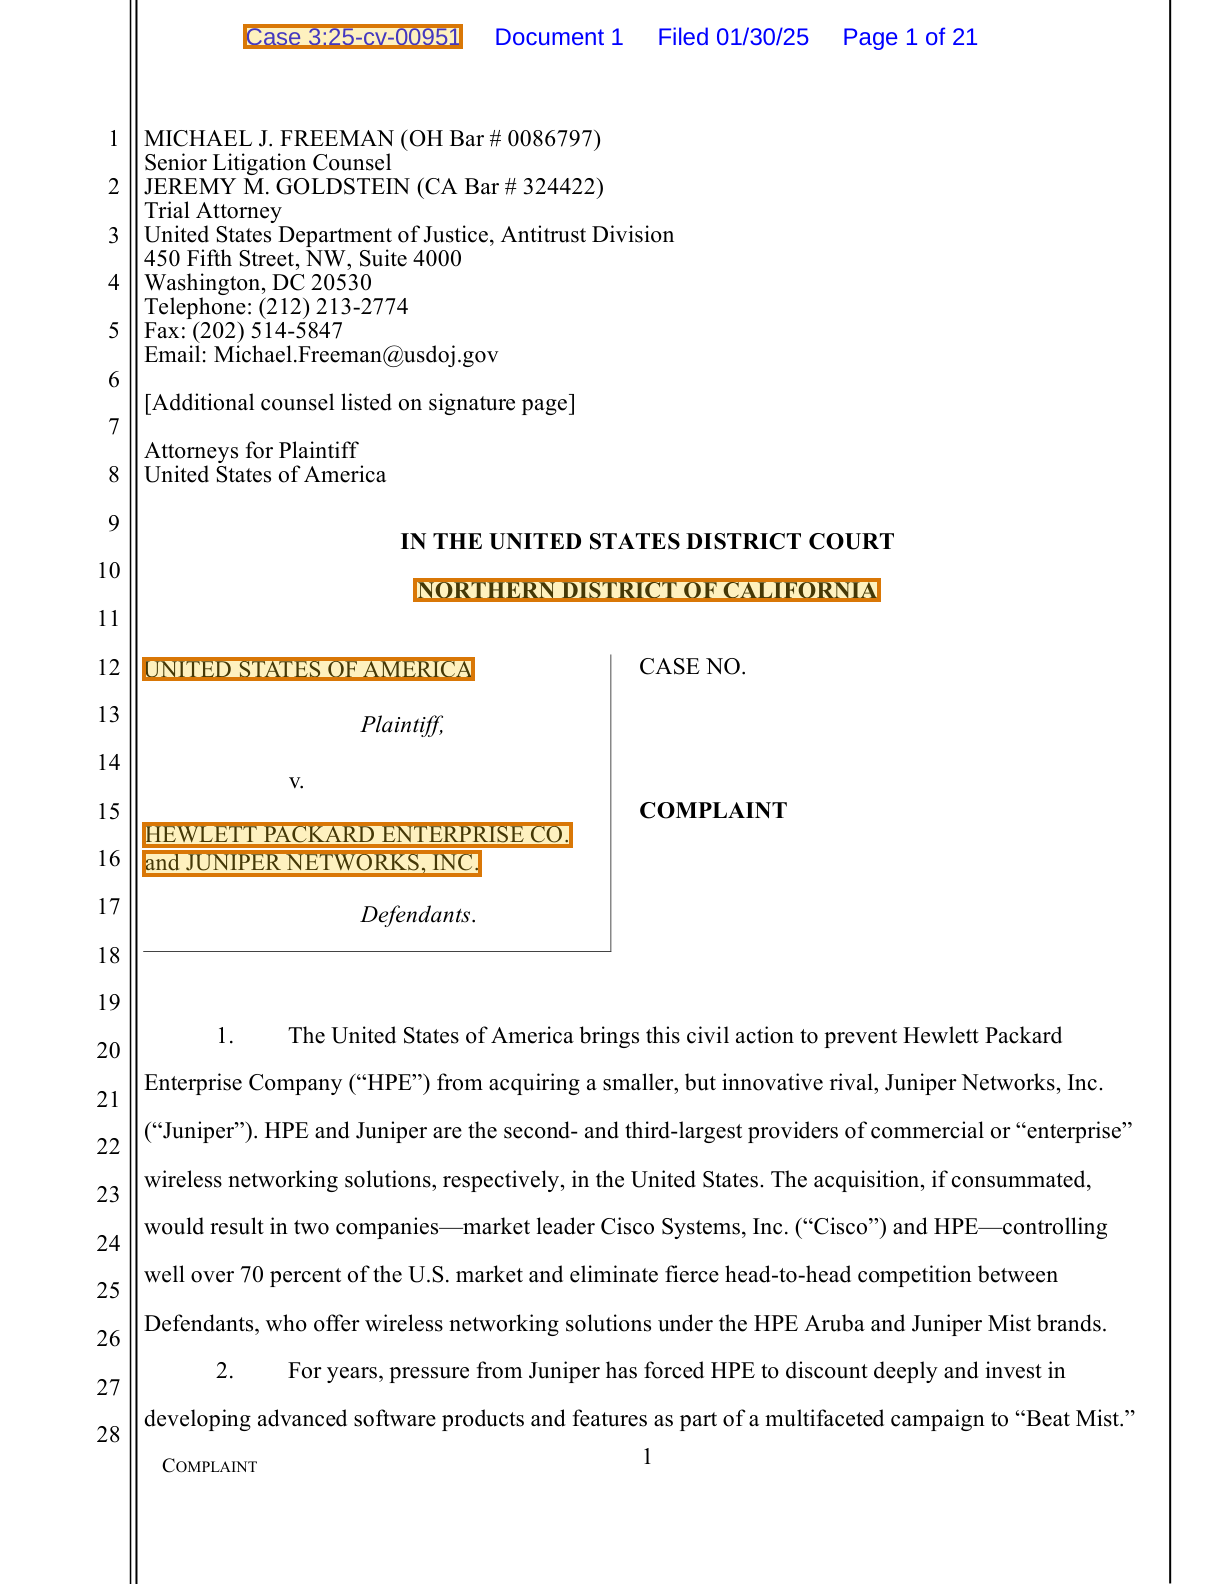
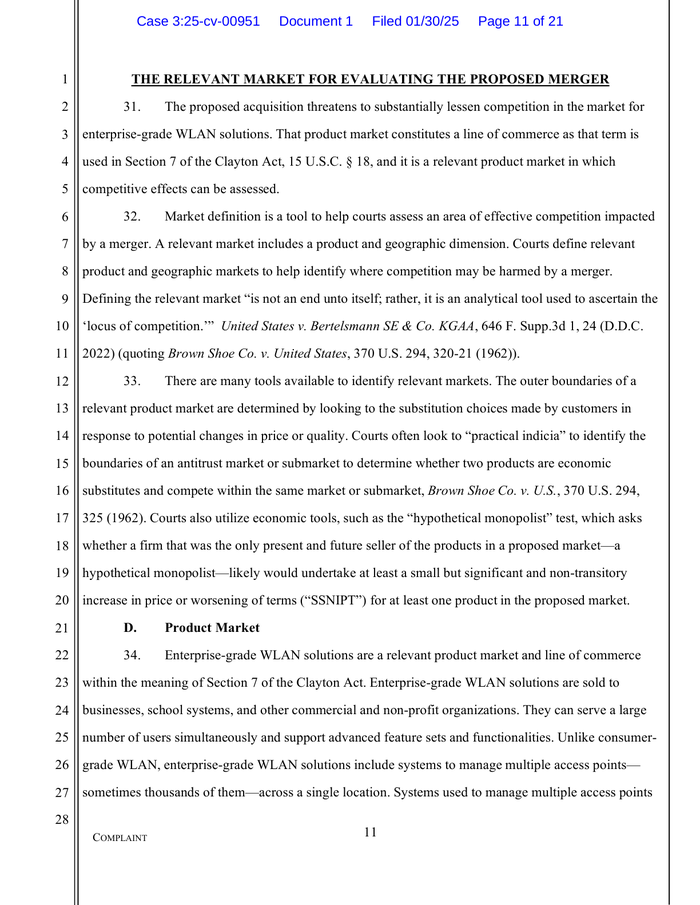
California courts require numbered lines down the left margin. A footer title and the court's filing stamp add more text outside the pleading itself.
Claims live in numbered prose
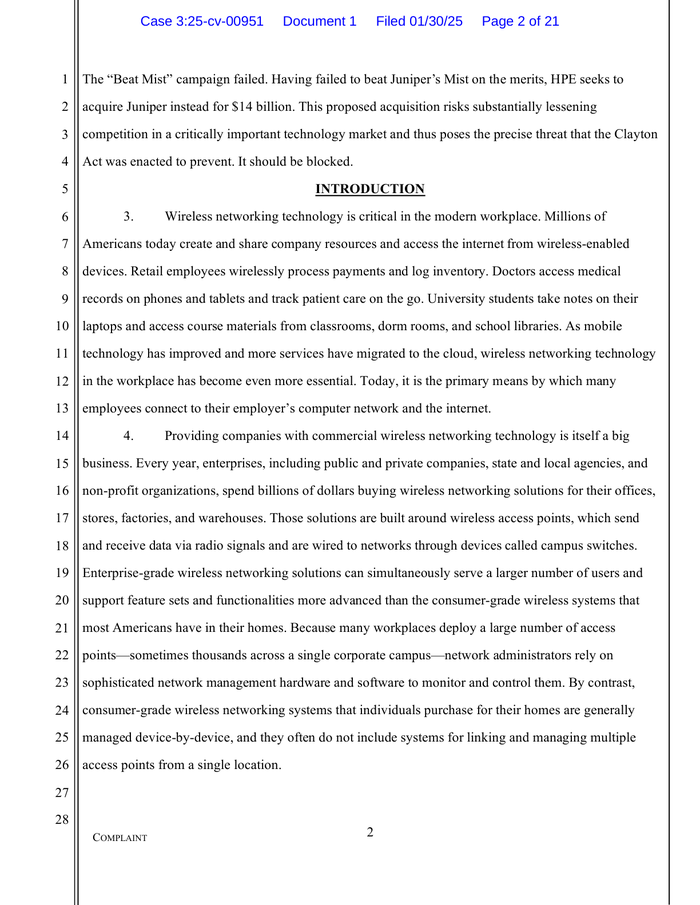
A complaint sets out its claims and the facts behind them across dozens of numbered paragraphs, with headings that vary by drafter.
The caption packs the parties
The caption sets every party in a box beside the case number, and a multi-party suit can carry it onto a second page.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One litigation complaint, end to end
About this document: The Justice Department's antitrust complaint against Hewlett Packard Enterprise and Juniper Networks, filed in the Northern District of California to block HPE's acquisition of Juniper. Its 21 portrait pages sit on numbered pleading paper, with the court's filing stamp across the top of each. Page 1 carries the caption, and numbered paragraphs of allegations run to the request for relief. Page 1 is featured.
Processing objective: The objective is to identify the case from its caption: which court, which docket and who is suing whom. The caption's case number box is blank, as on any complaint at filing, so the number comes from the court's filing stamp at the top of the page.
Demonstration fields: Court, Case number, Plaintiff, First defendant, Second defendant
The document
4 of 21 pages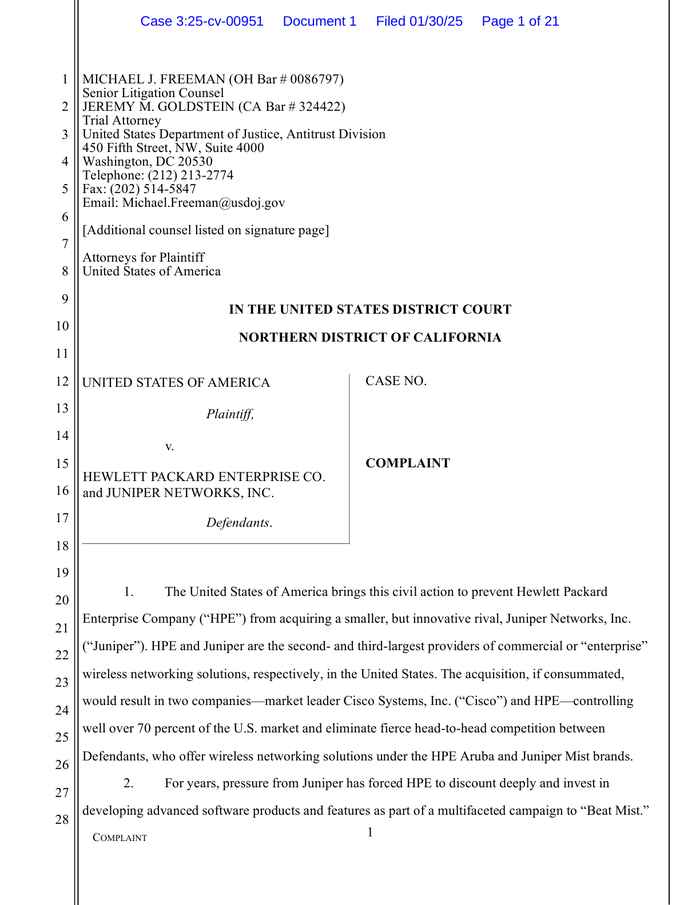 Page 1shown below
 Page 2
 Page 11
 Page 20
Where each value came from
court_district
{
  "value": "NORTHERN DISTRICT OF CALIFORNIA",
  "page": 1,
  "range": {
    "end": 538,
    "start": 507
  },
  "box": {
    "xmin": 0.33781,
    "ymin": 0.36525,
    "xmax": 0.71923,
    "ymax": 0.37989
  }
}case_number
{
  "value": "3:25-cv-00951",
  "page": 1,
  "range": {
    "end": 18,
    "start": 0
  },
  "box": {
    "xmin": 0.19888,
    "ymin": 0.01537,
    "xmax": 0.3777,
    "ymax": 0.03046
  }
}plaintiff
{
  "value": "UNITED STATES OF AMERICA",
  "page": 1,
  "range": {
    "end": 565,
    "start": 541
  },
  "box": {
    "xmin": 0.11679,
    "ymin": 0.41531,
    "xmax": 0.38746,
    "ymax": 0.42964
  }
}defendants[0]
{
  "value": "HEWLETT PACKARD ENTERPRISE CO.",
  "page": 1,
  "range": {
    "end": 611,
    "start": 581
  },
  "box": {
    "xmin": 0.11657,
    "ymin": 0.51913,
    "xmax": 0.46749,
    "ymax": 0.53514
  }
}defendants[1]
{
  "value": "JUNIPER NETWORKS, INC.",
  "page": 1,
  "range": {
    "end": 638,
    "start": 612
  },
  "box": {
    "xmin": 0.11618,
    "ymin": 0.53697,
    "xmax": 0.39346,
    "ymax": 0.5536
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.