Extracting data from life insurance applications
Each life insurer prints its own application form for the proposed insured and the cover requested, and files separate editions of it state by state. A large carrier's new business team receives thousands a month, one with every case an agent submits. They arrive as e-application PDFs, faxes or scanned paper.
New business needs the proposed insured, the owner, each beneficiary and share, the product, the face amount and the premium mode. The underwriting workbench uses them to order evidence and rate the risk, and the policy administration system issues the contract from them.
What makes life insurance applications hard
Answers are ticked boxes
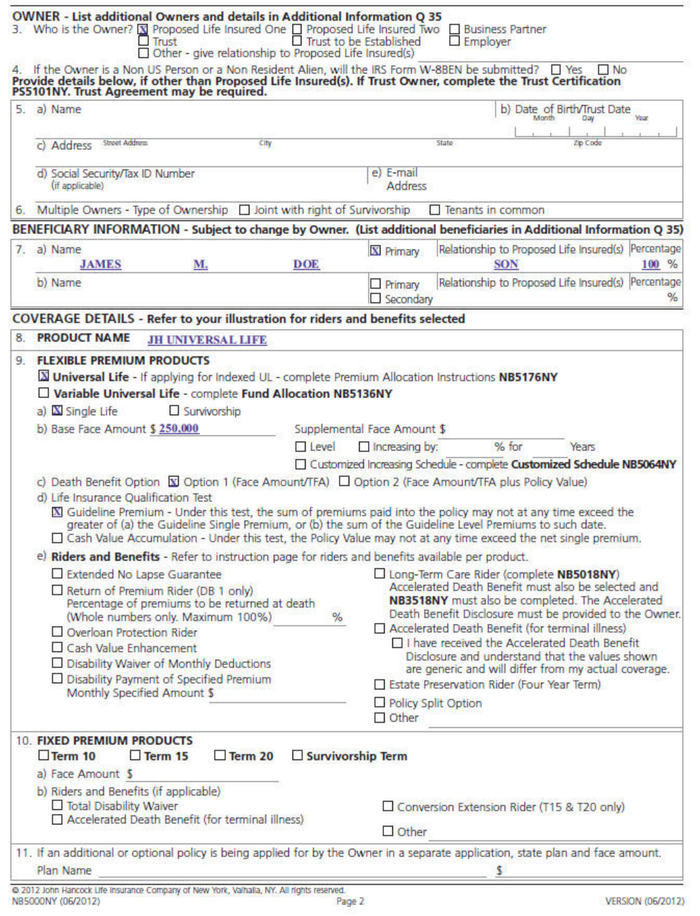
Ownership and every yes or no question are answered by a mark in one box, with several printed options sharing a single line.
Comb boxes and split blanks
Paper applications print many fields as comb boxes, one character per box, and split each name across a separate blank for every part.
Each carrier and state differs
Every carrier sequences its sections differently and files state editions of each form, so the same question sits somewhere new on each version.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One life insurance application, end to end
About this document: A John Hancock Application for Life Insurance, filled in by the carrier with specimen data and filed publicly with the SEC. Seven portrait pages, scanned at low resolution. The parties and the coverage fill pages 1 to 3, followed by the underwriting questions and the declarations. Page 2 is featured. Two specimen phone numbers and an email address were replaced with stand-ins.
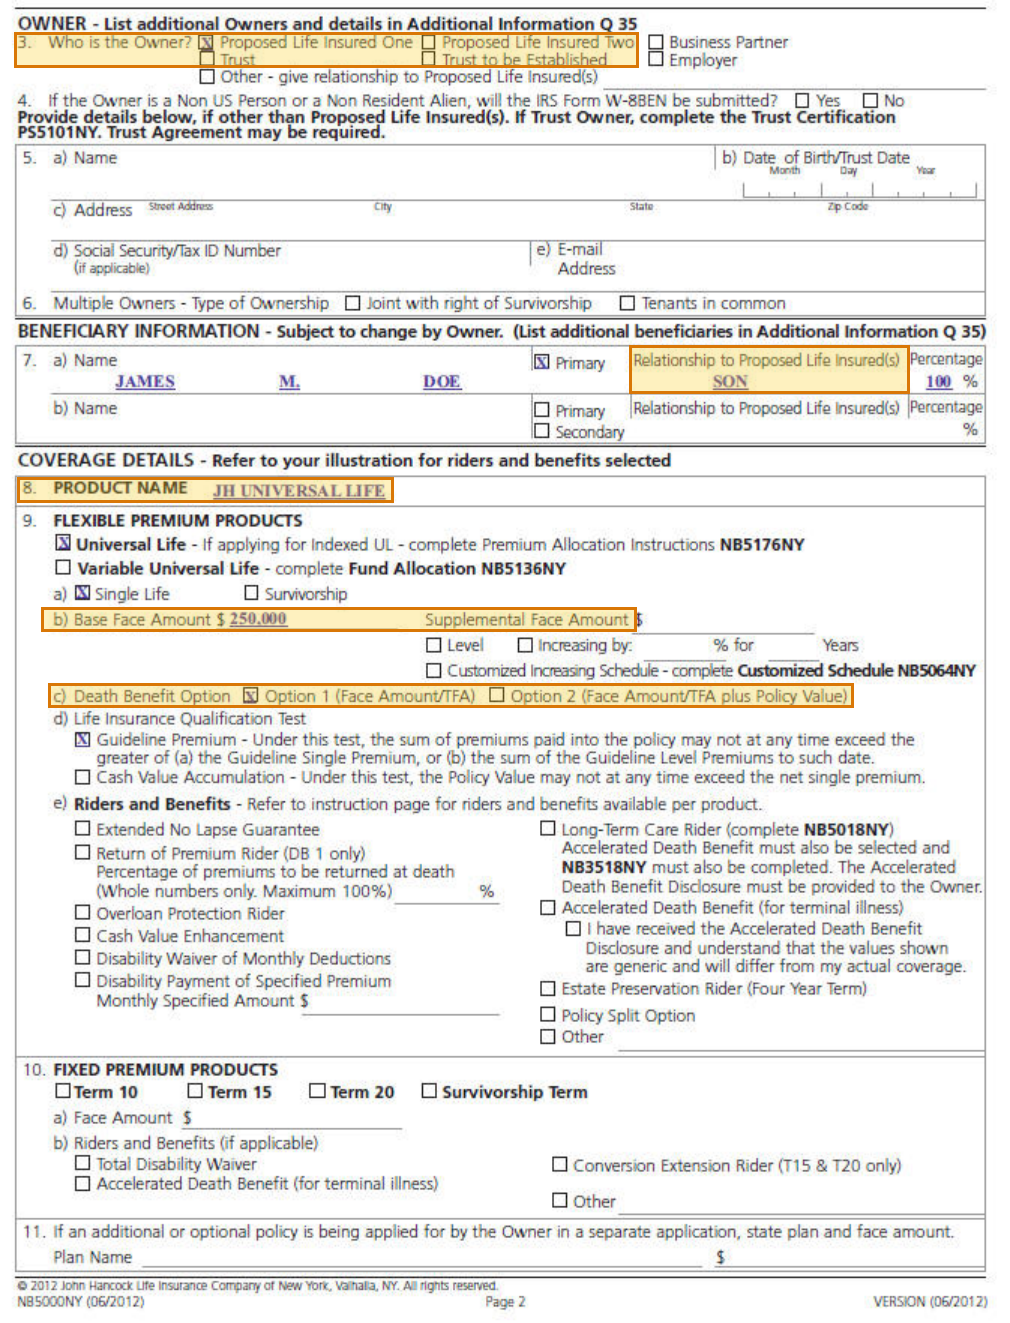
Processing objective: The objective is to read who owns the policy, who is paid if the insured dies, and how much cover is bought. Ownership and the death benefit option are ticked boxes. The product and face amount are typed into blanks beside them, and each value grounds to its own line of the form.
Demonstration fields: Policy owner, Primary beneficiary relationship, Product name, Base face amount, Death benefit option
The document
4 of 7 pages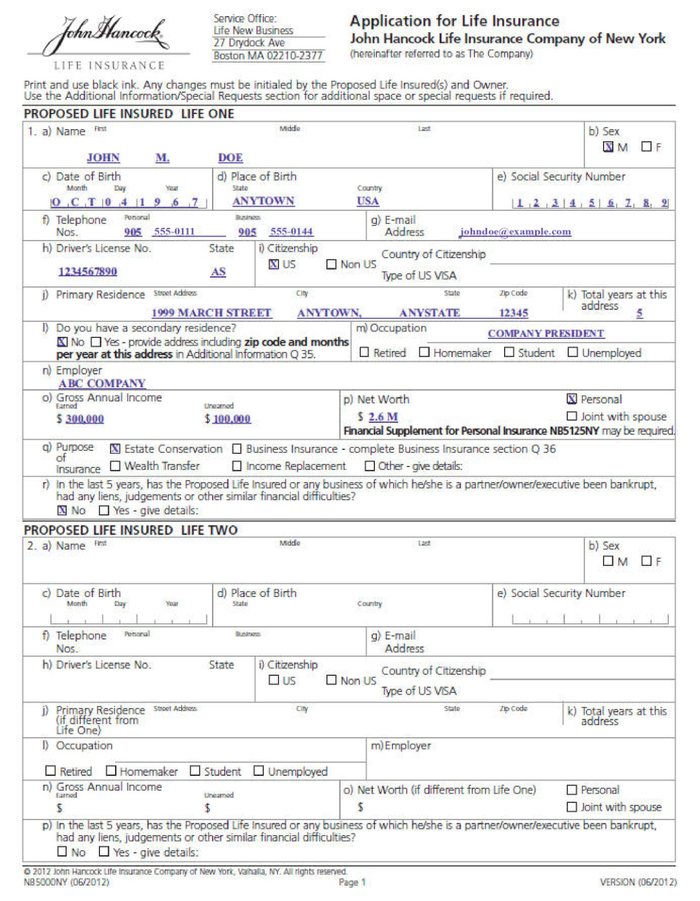 Page 1
 Page 2shown below
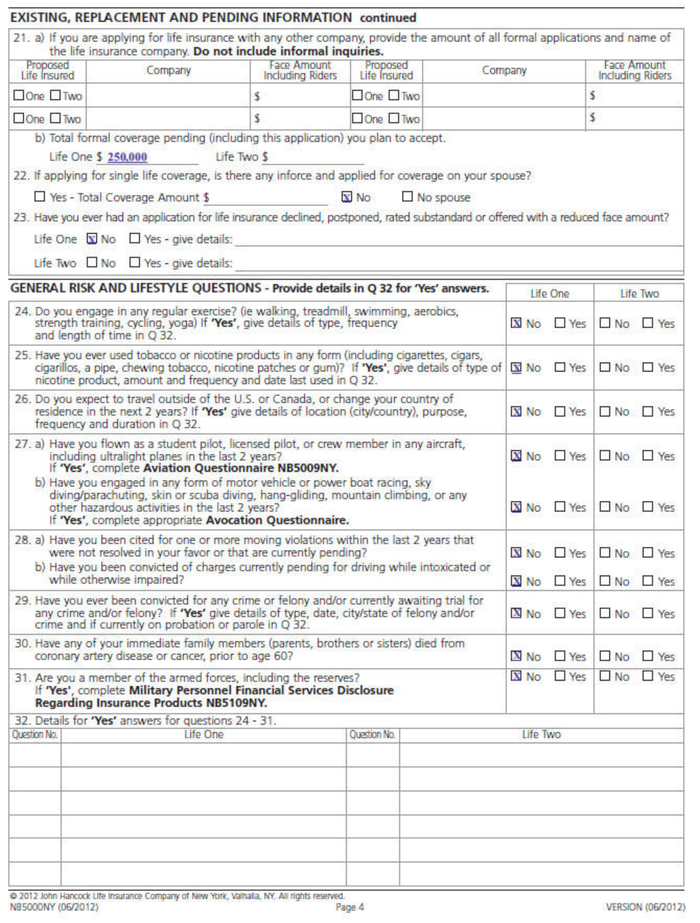 Page 4
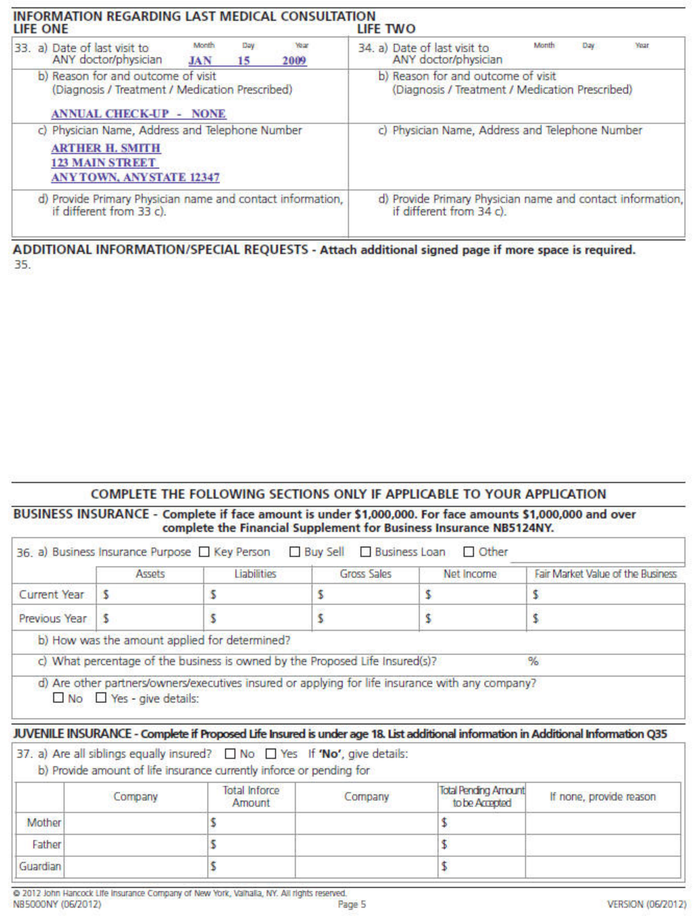 Page 5
Where each value came from
owner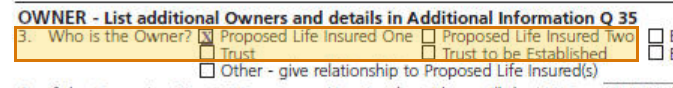
{
  "value": "Proposed Life Insured One",
  "page": 2,
  "range": {
    "end": 4348,
    "start": 4244
  },
  "box": {
    "xmin": 0.01429,
    "ymin": 0.02467,
    "xmax": 0.63223,
    "ymax": 0.0511
  }
}beneficiaries[0].relationship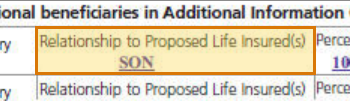
{
  "value": "SON",
  "page": 2,
  "range": {
    "end": 5265,
    "start": 5221
  },
  "box": {
    "xmin": 0.62371,
    "ymin": 0.26145,
    "xmax": 0.9,
    "ymax": 0.29776
  }
}coverage.product_name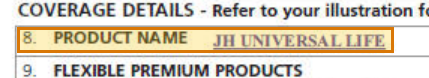
{
  "value": "JH UNIVERSAL LIFE",
  "page": 2,
  "range": {
    "end": 5579,
    "start": 5545
  },
  "box": {
    "xmin": 0.01703,
    "ymin": 0.36065,
    "xmax": 0.39006,
    "ymax": 0.37983
  }
}coverage.base_face_amount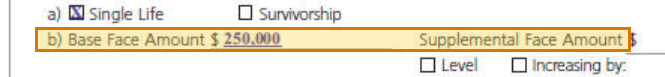
{
  "value": 250000,
  "page": 2,
  "range": {
    "end": 5844,
    "start": 5814
  },
  "box": {
    "xmin": 0.04137,
    "ymin": 0.45906,
    "xmax": 0.63007,
    "ymax": 0.47719
  }
}coverage.death_benefit_option
{
  "value": "Option 1 (Face Amount/TFA)",
  "page": 2,
  "range": {
    "end": 6096,
    "start": 5991
  },
  "box": {
    "xmin": 0.04767,
    "ymin": 0.51691,
    "xmax": 0.84482,
    "ymax": 0.53506
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.