Extracting data from motor vehicle reports
Each state's motor vehicle agency issues its own driving record abstract, with its own layout and codes. Auto insurers order one for every driver on a new policy, and motor carriers review each commercial driver's record at least once a year. They arrive as PDFs from state portals or screening vendors.
Underwriting needs the license status, each suspension, and every conviction with its violation date, conviction date and points. A rating engine applies surcharges from those convictions, and a fleet's driver qualification file records them against the carrier's safety policy.
What makes motor vehicle reports hard
Every state prints its own abstract
Each state agency sets its own layout and violation codes, so the same stop sign conviction reads differently from state to state.
Events stack as record blocks
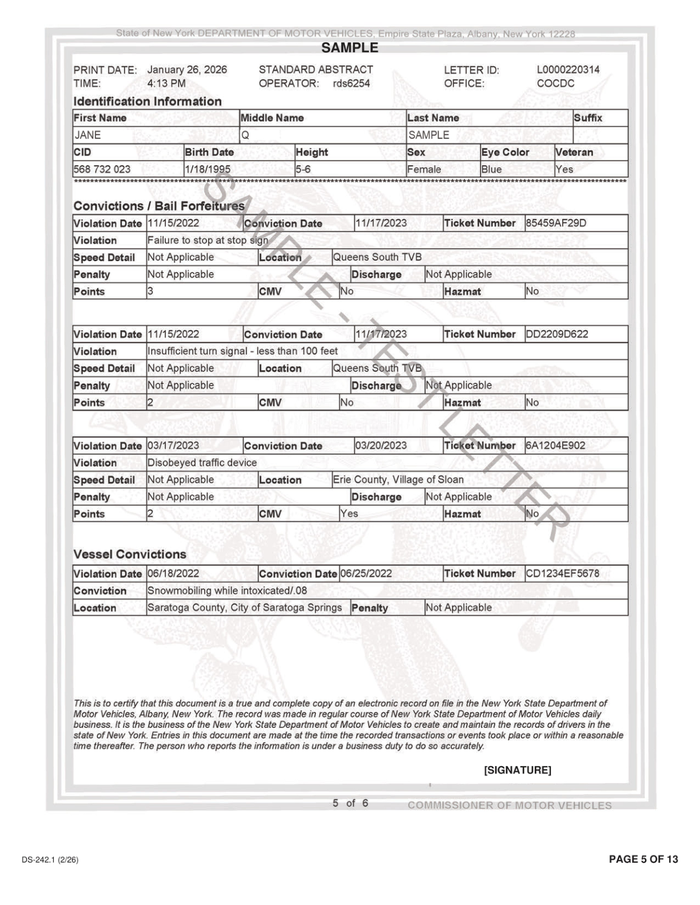
Events print as stacked label and value grids, one per conviction or suspension, and each grid is a single record.
Identification repeats on every page
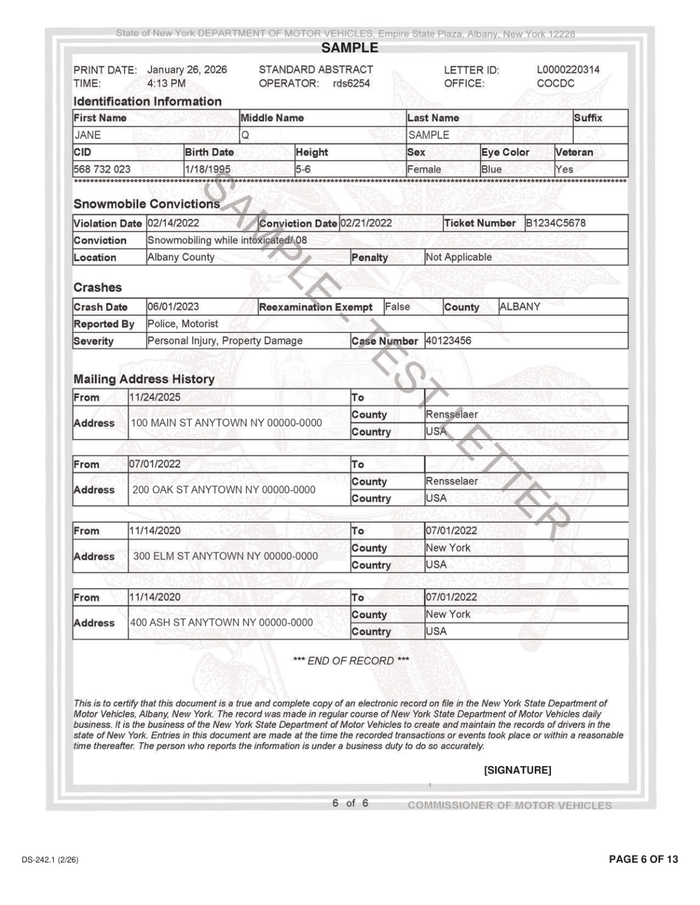
Abstracts reprint the driver's identification header at the top of each page, above whichever part of the record that page continues.
Parse, extract, verify
Parse
Parse turns the document into reading-order Markdown and a hierarchy of blocks (text, tables, figures), and grounds each block to its exact location on the page.
Extract
You define the fields in a JSON schema, and Extract returns their values in a consistent, structured format, each linked back to where it appears in the Markdown.
Verify
Each value links back to where it appears, down to the character range in the Markdown, and the page and bounding box in the source document, so every result can be verified.
One motor vehicle report, end to end
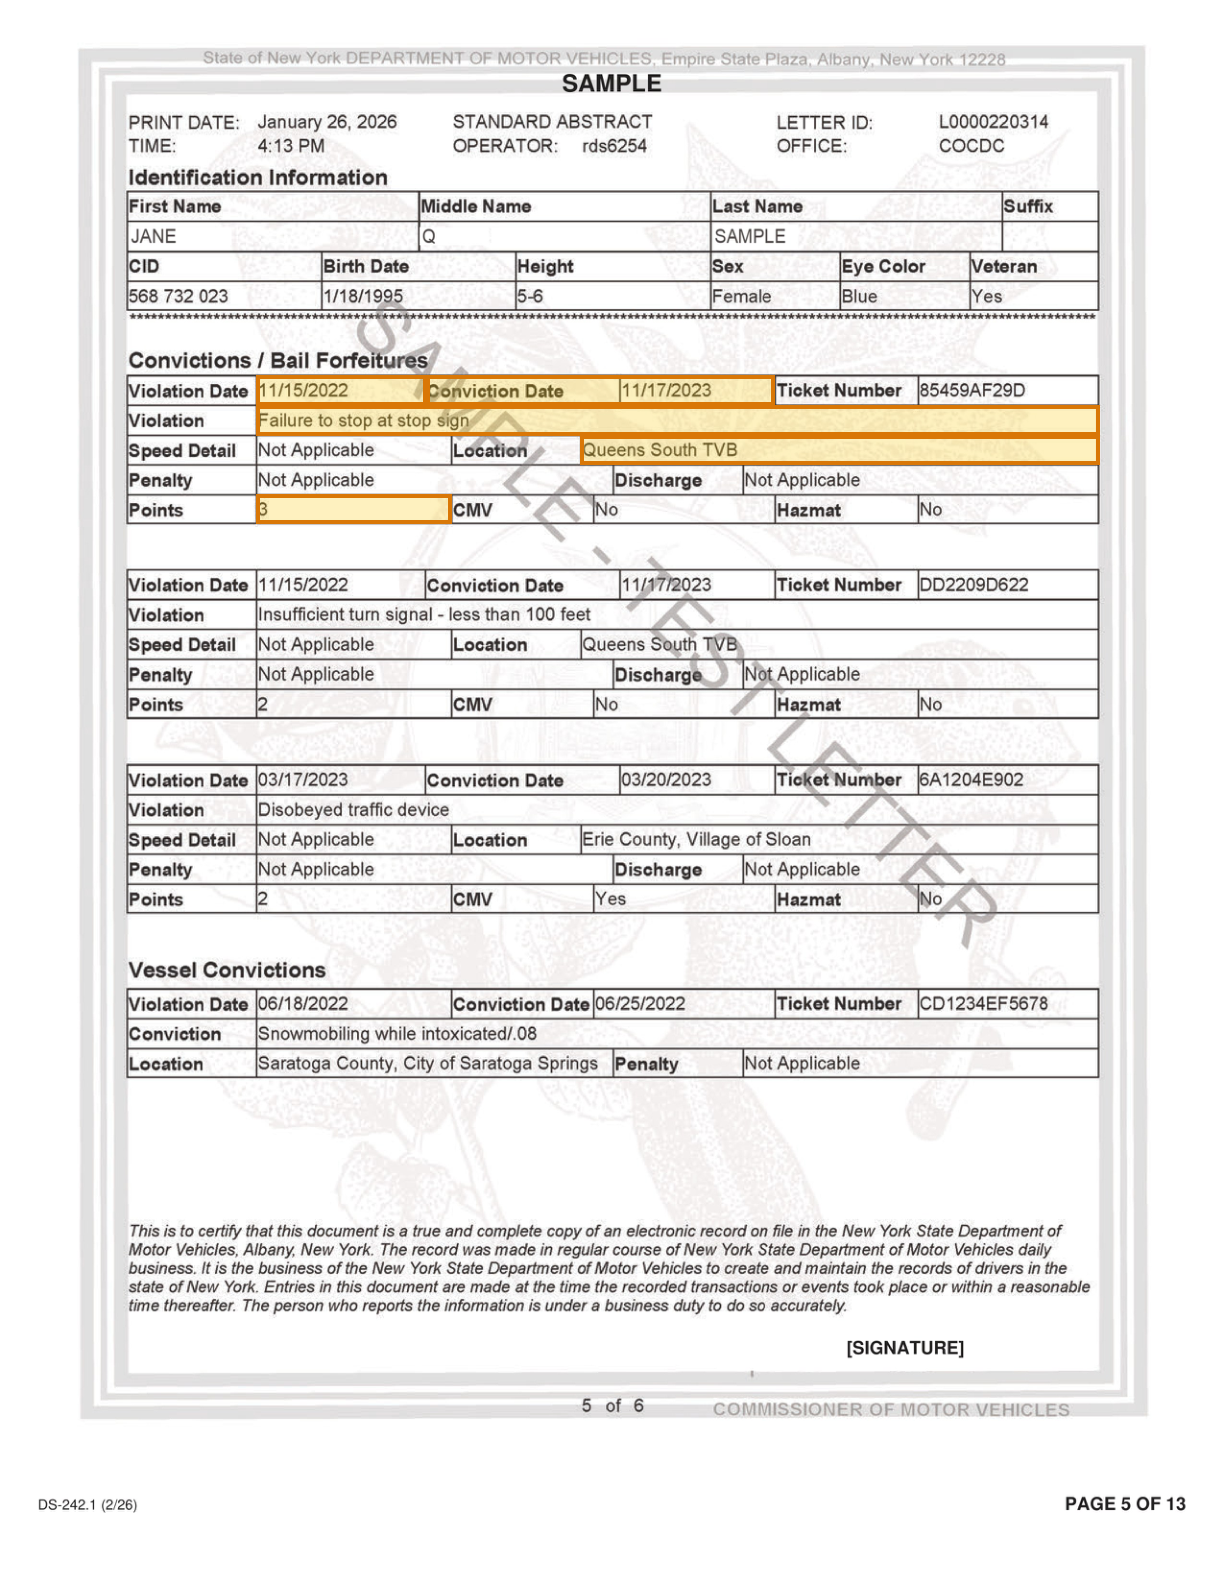
About this document: A sample standard abstract of a driving record, published by the New York State Department of Motor Vehicles to show what an abstract contains. Six portrait image pages under a diagonal SAMPLE watermark: status and credentials, suspensions, convictions, crashes and address history. Page 5 is featured. The specimen motorist's name and mailing addresses were replaced with stand-ins.
Processing objective: The objective is to read one conviction as a complete event. It records when the violation happened, when the driver was convicted, what the violation was, where it was heard and how many points it added. Each value grounds to the line of the conviction block that prints it.
Demonstration fields: Violation date, Conviction date, Violation, Court location, Points assessed
The document
4 of 6 pages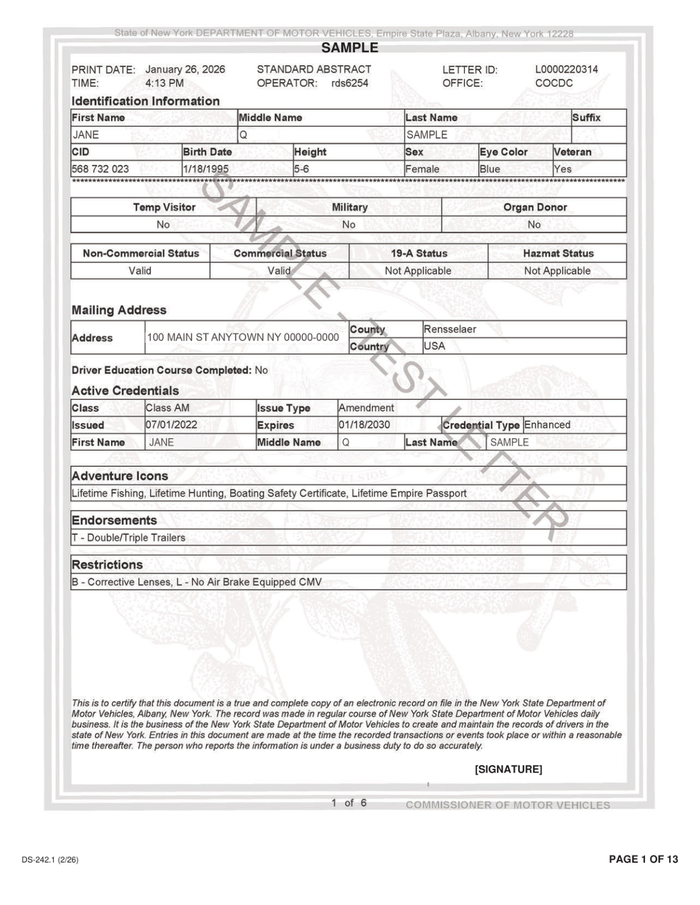 Page 1
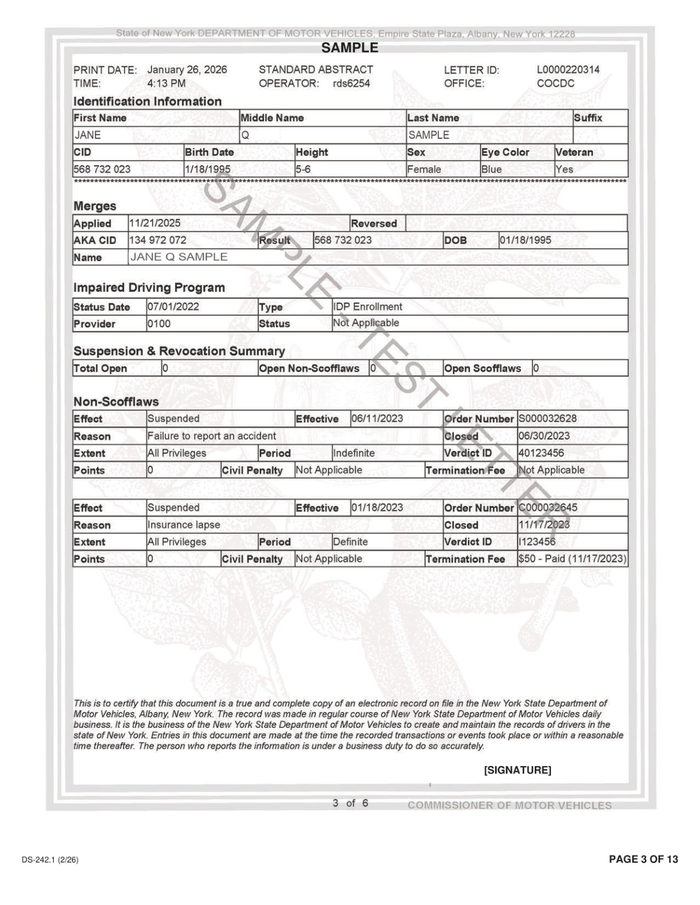 Page 3
 Page 5shown below
 Page 6
Where each value came from
convictions[0].violation_date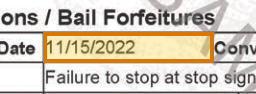
Printed on the page as 11/15/2022, normalized on extraction.
{
  "value": "2022-11-15",
  "page": 5,
  "range": {
    "end": 11725,
    "start": 11715
  },
  "box": {
    "xmin": 0.2095,
    "ymin": 0.23705,
    "xmax": 0.34848,
    "ymax": 0.25591
  }
}convictions[0].conviction_date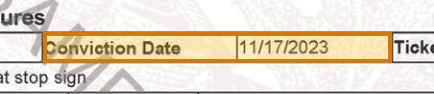
Printed on the page as Conviction Date | 11/17/2023, normalized on extraction.
{
  "value": "2023-11-17",
  "page": 5,
  "range": {
    "end": 11774,
    "start": 11746
  },
  "box": {
    "xmin": 0.34848,
    "ymin": 0.23706,
    "xmax": 0.63297,
    "ymax": 0.25591
  }
}convictions[0].violation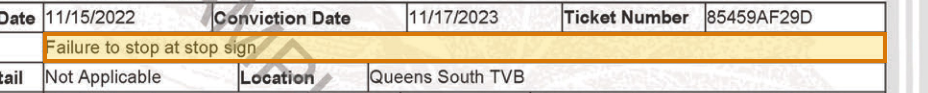
{
  "value": "Failure to stop at stop sign",
  "page": 5,
  "range": {
    "end": 11892,
    "start": 11864
  },
  "box": {
    "xmin": 0.20948,
    "ymin": 0.25591,
    "xmax": 0.89796,
    "ymax": 0.2748
  }
}convictions[0].location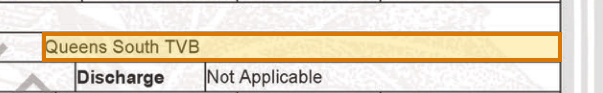
{
  "value": "Queens South TVB",
  "page": 5,
  "range": {
    "end": 12006,
    "start": 11990
  },
  "box": {
    "xmin": 0.47462,
    "ymin": 0.27478,
    "xmax": 0.89796,
    "ymax": 0.2933
  }
}convictions[0].points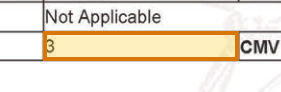
{
  "value": 3,
  "page": 5,
  "range": {
    "end": 12167,
    "start": 12166
  },
  "box": {
    "xmin": 0.20947,
    "ymin": 0.31238,
    "xmax": 0.36928,
    "ymax": 0.33038
  }
}
How to try it yourself
Everything on this page is reproducible. The sample, its schema, and the Parse and Extract API outputs are published. You can repeat the same two calls from whichever surface you already build on.
- Claude Skilldescribe the job; the agent writes it
- CLIno code at all
- MCPexpose ADE docs as an agent tool
- REST APIany language
- Pythonlandingai-ade
- TypeScriptlandingai-ade
Documents into data
Accurate
The best accuracy on the difficult documents other tools get wrong, such as messy scans, complicated tables, checkboxes and handwriting.
Auditable
Every answer cites its sources. Values come back with an audit trail (page, bounding box, character range) so a human can review them.
Agentic
Applies multi-step reasoning, and plans before it acts. Handles documents it has never seen before and adapts to variations.
API-first
Composable APIs that drop into any tech stack and can be called from anywhere. Easy to build on and embed in your pipelines and products.
Affordable
Cost-competitive rates with complete price transparency. Spend controls before you run, and every job reports its exact cost.
Enterprise-grade
Built for production and scale from day one. Fully observable and monitored, running securely in our cloud or yours.
Built for high-volume, high-throughput production
- Zero data retention
- Priority rate limits
- Enhanced support
- VPC and on-prem deployment
Available on Team and Enterprise plans. VPC and on-prem deployment require an Enterprise plan.